When a B2B marketing team plans a new content push, the first reflex is usually to check monthly search volume in a keyword tool or run a quick comparison in Google Trends. If the search volume reads zero or the trend chart looks flat, the topic often gets cut before anyone writes a brief.
In Answer Engine Optimization (AEO), improving how AI systems retrieve and cite your company's expertise, using search volume as a gatekeeper filters out the exact questions your buyers are asking. Search tools record the shorthand phrases people type into a traditional search bar, not the multi-part questions, technical constraints, and deal objections buyers bring to AI assistants, peer forums, and sales calls.
Traditional keyword research and Google Trends still have useful jobs: keyword volume helps size established search topics, and Google Trends tracks directional seasonality within a single market. On their own, however, neither measures AI prompt demand or suffices to validate a specialized B2B content category. To decide what to publish before committing months of budget, start with buyer questions that recur across independent conversations, then weigh keyword data as one input alongside commercial fit, internal expertise, and existing visibility.
What 59,515 keywords did and didn't reveal
An exhaustive keyword plan describes the answers traditional search results already hold, but it misses the specific objections and trade-offs buyers raise during active deals. We saw this firsthand when we reverse-engineered an SEO agency's content plan for an enterprise cybersecurity company.
The agency's work was sophisticated, not a superficial keyword export. The agency appears to have started with a detailed brand book mapping the company's target customers, products, competitors, pain points, and differentiators, and crawled over 900 pages on the company's website to benchmark existing coverage. From that foundation, the spreadsheet built out:
- 98 seed keywords: Core categories (managed detection and response, third-party risk management, digital risk protection), technologies (Microsoft Sentinel, Microsoft Defender), customer problems (alert fatigue, false positives, supply-chain risk), competitor names, acronyms, and commercial modifiers.
- 59,515 relevant keywords: Expanded terms tagged with search volume, keyword difficulty, intent, funnel stage, relevance, and a proposed title.
- 17,463 topic clusters: Grouped keywords with combined search volume and SERP gap analysis examining what ranking pages covered or lacked.
- 15,326 recommended pieces of content: Detailed content briefs with proposed angles, structure, word counts, internal links, and schema, including 2,373 programmatic SEO opportunities.
The SERP analysis surfaced commercially credible topics and real gaps in existing search results, such as missing pricing transparency and shallow implementation explanations. Yet the spreadsheet assigned every recommendation a score that appeared to be based on three variables: relevance to the company, keyword volume, and keyword difficulty.
Those three metrics could not answer what the client actually needed to know: which of those 15,326 possible articles represented its real buyers, tied to a strategic product, or would move pipeline. Because the briefs were derived from pages already ranking on Google, they were built to summarize existing answers more comprehensively rather than extract what the company's experts knew that search results omitted.
A keyword opportunity tells you that somebody may want an answer. It does not tell you whether that person is your buyer, whether the question matters commercially or whether your company should be the one answering it.
On a discovery call, a prospect tells a salesperson: "We already own Microsoft E5. Why do we need to pay someone else to manage it?" That objection is commercially decisive, and answering it with clear architectural trade-offs can shape both live deals and AI answers about when managed security services are worth paying for. That objection may never appear as a high-volume keyword, just as repeated Reddit discussions about excessive alert tuning, opaque MDR pricing, or disappointing incident-response support reveal evaluation criteria that rarely look like neat keyword clusters.
Starting with 59,515 keywords produced 15,326 possible pieces of content, but it did not, by itself, reveal the 30 questions most likely to influence the company's buyers or establish the company as an authoritative source in AI answers.
Why zero-volume questions are normal in AI search
Many of the sub-queries AI systems generate and the conversational prompts buyers submit register zero monthly search volume in traditional SEO tools, which means strict volume cutoffs can screen out questions AI systems actually research. Filtering topics by search volume assumes buyers use AI assistants the way they use a search box.
When buyers prompt ChatGPT, Perplexity, or Google AI Mode, they include context they would never type into a two-word keyword query: their existing security stack, headcount, compliance obligations, or workflow constraints. Behind the scenes, the AI engine expands that single prompt into multiple background searches to gather supporting facts, a process called query fan-out.
Those background searches rarely show up in keyword databases:
- 95% of fan-out queries show zero search volume: In a November 2025 study of 501 prompts run on the Gemini 3 API with Google Search grounding forced, Seer Interactive found that prompts generated an average of 10.7 fan-out queries (ranging from 3 to 28 and averaging 6.7 words), and 95% of those queries had zero tracked global monthly search volume. (Because grounding was forced for the API test, the study measures what fan-out queries look like when search retrieval runs, not how often Gemini relies on training data alone.)
- Single prompts expand into multiple sub-queries: Ahrefs' analysis of query fan-out cites research from Seer Interactive and Nectiv finding an average of 9 to 11 fan-out queries per prompt, with over 95% receiving no recurring searches.
- AI prompt volume is not publicly disclosed: You cannot simply replace keyword volume with an "AI prompt volume" column. Major LLM providers like OpenAI do not release user query logs, so buyers evaluating tracking platforms on our sales calls treat prompt-volume figures as directional estimates rather than verified counts.
As we detail in our comparison of four methods AEO tools use to generate tracking prompts, every demand metric in an AEO dashboard has structural limits. Converting SEO keywords into sentences still relies on rounded Google Keyword Planner monthly buckets from traditional search. Tools that sample opt-in AI conversation panels, such as Profound (which describes licensing double-opt-in consumer panels and applying statistical adjustments) or Scrunch, weight and extrapolate sampled interactions to estimate broader demand. A large panel can capture substantial consumer activity while containing limited evidence about a specialized enterprise buying role, and Scrunch's methodology discloses that when panel observations are sparse, its estimator falls back to external search-demand signals and similarity to known topics.
What Google Trends can and can't tell you
Google Trends is not reliable on its own for keyword selection or AEO demand validation because it reports a normalized 0 to 100 relative index rather than search volume, can produce misleading spikes in small regions on low-interest queries, and excludes internal AI Mode and AI Overviews searches entirely.
Marketers checking niche B2B terms sometimes see a small market like Cheyenne, Wyoming show up as the #1 region for unrelated topics. Commentators often attribute those anomalies to local data centers, proxy routing, or bot traffic, though without citing primary data from Google.
Rather than attributing small-region spikes to data centers, Google's Trends data FAQ documents how Trends samples, normalizes, and filters search data, pointing to four mechanics that affect small geographies and AEO planning:
- Regional total-search normalization: Each data point is divided by the total searches of the geography and time range it represents, then scaled from 0 to 100. Because every region is divided by its own search volume, regions with the same relative score do not have the same total search volume, and a small number of searches in a small market can outweigh a much larger count in a populous state.
- Statistical privacy noise and rare automated activity: To protect user privacy, Google incorporates statistical noise (small random fluctuations that do not represent actual search behavior), which is most noticeable on queries with low or no search interest. Google also notes that in rare cases irregular automated queries are retained in Trends as a security measure so those issuing them cannot tell they have been identified.
- Low-volume and character filtering: Trends only displays data for popular terms, so low-volume terms appear as "0," repeated searches from the same person are dropped, and queries with apostrophes or special characters are filtered out.
- No AI Mode or AI Overviews data: Google Trends filters out searches made by Google products and services, which explicitly includes internal searches made by AI Mode and AI Overviews.
Use Google Trends to check macro seasonality, long-term trajectory, or relative popularity between established terms inside a single large market. Do not use it to size topic demand, pick geographic targets for niche terms, or gauge what AI search systems are querying.
Validate a new category with recurrence, not a waitlist benchmark
When you need to validate demand for a new content category before committing months of budget and developer time, a practical test alongside search and landing-page checks is whether the same underlying need recurs across independent buyers and channels, especially sales calls. While cross-source recurrence does not prove population-level search demand, it connects a proposed topic directly to problems target accounts are trying to solve.
Startup validation playbooks often recommend checking keyword volume, conducting customer interviews, and launching a smoke-test landing page to see whether visitors sign up for a waitlist, often citing a 2% to 5% conversion benchmark. Those tactics have real uses: keyword research shows whether adjacent search demand already exists, interviews surface pain points, and a landing-page test can gauge interest in a standalone newsletter, template, or resource hub. However, the 2% to 5% waitlist benchmark is widely repeated without a cited empirical source, and neither test is sufficient on its own when buyers in an emerging B2B category still search for operational symptoms rather than your category label.
Rather than relying on search volume or cold-ad waitlists alone, pair them with a four-step recurrence check across buyer conversations:
- Mine existing buyer conversations across channels: Review discovery and sales call recordings, support tickets, Reddit threads, and LinkedIn discussions for repeated operational problems. When enterprise legal teams cannot share raw sales call transcripts, webinar Q&A transcripts provide a practical alternative. For the full extraction workflow, see our guide on how to mine sales calls, Reddit and support tickets for the questions buyers ask AI and our comparison of AnswerThePublic vs AlsoAsked vs Reddit mining tools.
- Test for cross-source corroboration: Different channels surface different slices of buyer need. In our sales calls, buyers note that pricing and commercial flexibility questions consistently come up in live conversations rather than online. In an anonymized cybersecurity sample we analyzed, 61 relevant LinkedIn posts yielded 58 buyer prompts and 937 Reddit posts yielded 67 prompts across 20 recurring themes. Separately, in an anonymized cybersecurity project documented in our AI visibility prompt-set guide, eight prompts sat beneath an Employee-Driven Vulnerability Remediation theme, and seven of those eight recurred across multiple sources, including sales calls.
- Count independent ICP buyers, not loud voices: Six comments from one vocal participant in a subreddit thread do not equal six independent buyers, and social engagement does not prove buying intent. Verify that the people raising the issue match your ICP and that the question came from the buyer rather than being introduced by a salesperson.
- Publish one expert-led pilot piece before building a hub: Before investing developer time in a new resource center, publish a single substantive article or comparison answering the recurring question, share it in active deals, and track whether buyers engage with it and whether AI engines cite it.
Because each demand signal measures a different behavior, B2B teams get the clearest read when they match each source to what it can actually prove:
| Demand signal | What it actually measures | Where it breaks for AEO | Best role in B2B content planning |
|---|---|---|---|
| Traditional keyword volume | Rounded monthly Google search counts for established terms and close variants | Misses conversational constraints, sales objections, and zero-volume fan-out sub-queries (95% had zero volume in Seer Interactive's Gemini 3 study) | Sizing established search topics and aligning SEO with AEO coverage |
| Google Trends (0–100 index) | Relative share of total Google searches in a given region and timeframe | Excludes AI Mode and AI Overviews searches; small-sample normalization and privacy noise distort niche queries | Checking macro seasonality and momentum within one large geography |
| AI conversation panels | Sampled prompts from opt-in AI users, weighted to estimate broader topic demand | Coverage of specialized enterprise roles varies; when panel observations are sparse, estimators such as Scrunch fall back to search-demand signals | Observing how sampled users phrase prompts in broader categories |
| Smoke-test landing page | Click-through and email signup rates from cold ad or social traffic | Tests interest in an offer or format rather than the specific questions AI engines retrieve and cite; common 2%–5% waitlist benchmarks lack a cited source | Testing willingness to sign up for a standalone newsletter, tool, or paid course |
| Cross-source buyer recurrence | How often independent ICP buyers raise the same need across calls, tickets, Reddit, and LinkedIn | Does not establish population-level AI prompt volume across the entire market | Validating new content categories and prioritizing high-intent AEO topics |
Score questions on four kinds of evidence
Traditional keyword research is still worth doing when search volume is treated as one scoring input alongside buyer, commercial, expertise, and visibility evidence, rather than the gatekeeper that decides what gets written.
Practitioners are increasingly replacing single-metric volume cutoffs with multi-signal scoring. In CXL's AI search strategy framework, Alex Birkett scores candidate topics from 1 to 10 across three checks: buyer data (customers ask it repeatedly), product alignment (your solution credibly solves it), and channel validation (search volume, citation activity, or forum discussions exist).
At Rocksalt, we evaluate candidate questions across four kinds of evidence to narrow thousands of possibilities down to the questions worth answering:
- Buyer evidence: Does the question appear repeatedly across sales calls, customer meetings, webinar Q&As, LinkedIn discussions, or Reddit communities among people who match your ICP? Recurrence counts show cross-source corroboration in the evidence reviewed, not population-level AI search volume.
- Commercial evidence: Is the question tied to a problem your company solves, an evaluation criterion, or an objection that stalls deals? Which stage of the buying journey (awareness, research, or decision) does it influence?
- Expertise evidence: Does your team have operational data, implementation failure patterns, anonymized customer examples, or a trade-off analysis that improves on existing search results? Because SERP-derived briefs only restate what already ranks, the missing knowledge sits with product leaders, sales engineers, security analysts, and customer teams, who in Rocksalt contribute answers directly via email or inline document comments.
- Visibility evidence: Where are existing answers weak or absent, and where should your expertise live? Google Search Central's guidance for AI search advises focusing on valuable, non-commodity content and first-hand expertise rather than publishing separate pages for every query variation, and cautions against pursuing inauthentic off-site mentions. Strong visibility plans pair canonical website pages and comparisons with credible expert participation in the Reddit and LinkedIn threads AI engines and buyers consult.
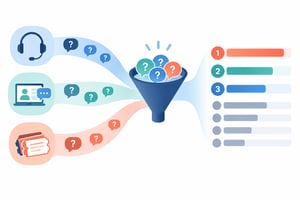
When narrowing a large list of surfaced questions down to an actionable publishing plan, Rocksalt scores each theme on three counts:
- Commercial intent: How many prompts in the theme have high commercial intent, meaning they're likely to produce a vendor recommendation.
- Question depth: How many prompts have multiple buyer questions behind them, a sign the question is popular.
- Source breadth: How many prompts are backed by multiple sources, a sign the need isn't confined to a single community or customer segment.
Once a customer connects their CMS, Rocksalt also checks each theme against what's already live on their website, so the plan separates questions existing pages already answer from gaps that need new or updated content.
A high-volume keyword with no buyer or commercial evidence may bring top-of-funnel traffic, but it is rarely an AEO priority. A zero-volume question that repeatedly stalls sales calls and lacks a credible technical answer online belongs at the top of the queue. For how to organize those chosen questions into a benchmark and a publishing roadmap, see our pillar guide on how to build an AI visibility prompt set from real buyer questions and our walkthrough on finding the sub-questions AI answers and choosing which to write.
Use search metrics to size topics, and buyer evidence to choose them
The agency keyword plan we reviewed was not poorly executed. It showed both how far automated keyword clustering and search-result analysis have come and where their ceiling sits: search data can tell you where an article might rank, but it cannot tell you which questions will actually move your buyers.
If your team is planning AEO content or testing a new content category this quarter, invert the usual research order. Start by pulling the questions, constraints, and objections that recur across sales calls, support conversations, and peer communities, before anyone opens a keyword tool or checks a trend chart.
Once you have that buyer-evidence list, use keyword research to check adjacent search phrasing and Google Trends to spot broad seasonal shifts, then put your budget where buyer recurrence, commercial value, and your internal experts' firsthand knowledge overlap.